August 19, 2026
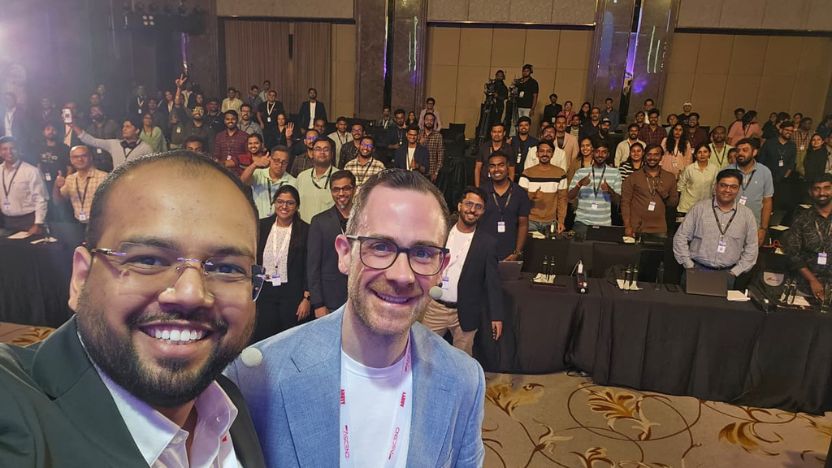
We ran a hands-on Prompt Activity session at the ABBYY Ascend Developers Conference (DevCon) in Bengaluru, India, July 2026, and it's the unexpected results that taught me the biggest lesson.
More than 75 developers in the room worked through the same exercise: use ABBYY Vantage's Prompt Activity for zero-shot extraction, no training required, on the same document type, over the same tenant and the same large language model (LLM) connection. Take the OCR-grounded document content from ABBYY, pass it through Prompt Activity, and review what the model returns. The energy in the room was genuinely great. People built a working extraction flow in minutes, on a document type they had never trained a model on. That's exactly what Prompt Activity is built to do, and it delivered.
What stayed with me came from the feedback and the conversations happening right there in the room, while people were still working through the exercise. As developers compared results with each other and with the ABBYY team mid-activity, something odd surfaced: they were running the identical exercise, on the identical setup, and landing on different results. Some had clean, accurate extractions. Others had fields that came back empty or came back with the wrong value entirely. Same tenant, same connection, same document, same instructions—so why did the outcome change from person to person?
That question is the real learning from the session, and it's worth sitting with rather than rushing past.
Jump to:
Why “LLM or IDP” is the debate we should stop having
Why LLM governance doesn't get lighter, it gets more specific
Match the technology to the document, not the other way around
The wrong question is "LLM or IDP?" Both belong in the same pipeline; the useful question is where each one does its job, and what surrounds it.
Traditional intelligent document processing (IDP) is strong on structured documents, stable layouts, and repeatable fields, the same output for the same input, every time. An LLM is strong on exactly the kind of thing the room was doing at DevCon: variable formats, zero training data, and a document type it had never seen before. Both of those are real strengths. What the feedback conversations surfaced is that they're different strengths, and an enterprise deployment needs both, not a choice between them.
The architecture behind that isn't a binary choice, it's a pipeline.
The zero-shot exercise we ran at DevCon is a real, proven piece of that pipeline. It's the fast, no-training entry point, and it's genuinely valuable on its own. What the conversations in the room pointed to is that it's the accelerator inside a larger framework, not the entire framework by itself. That's not a knock on the exercise. It's exactly what made it such a good teaching moment: a room full of developers got to build firsthand, what zero-shot extraction can do and where it needs support.
None of this works if an LLM is trusted blindly, and that's the piece the guardrails are for. These can include confidence thresholds that route uncertain fields to review, business-rule checks that catch a wrong value before it moves downstream (do the numbers reconcile, is the format valid, etc.), and a clear human-in-the-loop path for anything the system flags rather than resolves.
Governance isn't a tax on using an LLM. It's what turns a flexible but variable model into an extraction result the business can actually rely on.
The right approach considers matching the technology to the document, not the other way around: structured, high-volume content stays with rules and ML-based extraction; variable formats and no-training-data cases, like the one the DevCon room was solving, go to prompt-based extraction; and anything compliance-critical keeps deterministic extraction with human review.
Mixed document sets just mean a hybrid, per-document strategy instead of one method for everything.
Inside that framework, an LLM can absolutely be the default engine for a given step. What makes that safe isn't the model behaving well on its own, it's the guardrails, validation, and human review around it that let a fast accelerator operate like production infrastructure.
So why did the outcome change from person to person? Because an LLM-only setup is powerful, but not inherently deterministic. Without grounding, validation rules, workflow controls and human review, the same flexibility that makes it useful can also produce inconsistent or unreliable results.
I keep coming back to that session because it did exactly what a good hands-on exercise should do: it let people experience the real strength of zero-shot Prompt Activity, and it surfaced, through their own comparisons and conversations, exactly why that strength needs a framework around it at enterprise scale. That's not two separate lessons. It's one: LLMs are a genuine accelerator, and the framework around them is what makes that acceleration something you can build a business process on.
That's precisely the case for ABBYY. This activity didn't just showcase Prompt Activity - it reinforced why ABBYY provides the right foundation for enterprise AI automation. ABBYY put that LLM inside a pipeline already built on decades of high-quality OCR, document understanding, validation, and human-in-the-loop review. That is what makes the architecture practical. It's why, 75+ developers and one hands-on session later, I'm more convinced than ever that ABBYY is built for exactly this moment.
If you want to see Prompt Activity and this framework in action, it's available today inside ABBYY Vantage. Reach out to your ABBYY representative or see the documentation on configuring LLM connections and extracting data with prompt-based activities.
To explore what's possible across the full platform, visit abbyy.com/ai-document-processing.
Generic extraction tools are built only to pull text off a page, not to enforce structure, there's no schema and no validation step forcing output into defined fields. Messy output isn't a flaw, it's the direct result of what these tools are designed to do: extract, not structure.
As most of such PDF parsers run on general-purpose LLMs built for open-ended reasoning, not purpose-built for one deterministic task. Nothing in that design forces two runs onto the same path. Consistency has to be imposed from outside the model, not expected from it.
Components for data extraction already exist off the shelf, OCR handles the reading, LLMs now make language understanding easy, so anyone can assemble a working pipeline, the same way anyone can buy spare parts and build a car. What's hard isn't building a car; it's building one that meets a standard, performs reliably and can be trusted at scale.
Deepak Goyal
Partner Engagement & Innovation Consultant at ABBYY and a 2026 ABBYY MVP
With more than 10 years of experience in intelligent document processing (IDP), AI, and enterprise automation, Deepak works closely with partners and technology teams at ABBYY to drive innovation, develop integrations, and explore practical applications of AI and LLMs within intelligent automation workflows. He is also actively involved in partner enablement, technical workshops, webinars, and hands-on sessions, helping partners turn emerging technologies into practical business solutions.
His mission: help partners see what's actually possible with AI, and turn that into results that matter for their business.
You can get in touch with Deepak via LinkedIn.
